PLEKHA6
protein abundance — cross-omicsAcross TCGA patient cohorts, PLEKHA6 protein abundance is significantly associated with the RNA expression of many other genes, with 16,175 significant associations in total. CCRCC shows the largest number of these associations.
The most reproducible PLEKHA6-associated genes across cancer lineages are SELENBP1, GOLT1A, and GJB1. Each is linked with PLEKHA6 in more than 8 cancer types. Because this analysis shows association rather than direction, both PLEKHA6-to-partner and partner-to-PLEKHA6 results are reported.
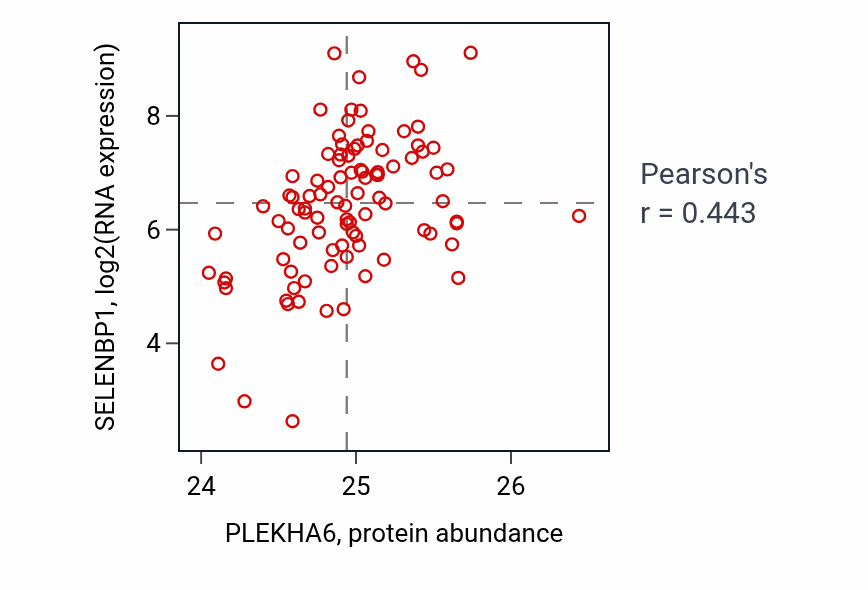
Each partner links to its own Q-omics profile. The scatter plot shows the strongest example, PLEKHA6 versus SELENBP1 in COAD, with a Pearson correlation of 0.44.
protein abundance associated genes by consensus
Ranked by combined sampling and lineage consensus. X-score (PLEKHA6→partner) and Y-score (partner→PLEKHA6) are standardized regression coefficients; both directions are reported because the association is undirected. p-values are from the association test.
Each partner links to its Q-omics profile. Showing the 6 strongest of 16,175 associations by consensus.